Delivery effectiveness
Task-to-merge time, reviewer effort, retries, and handoffs. We look for where AI-assisted work saves time and where it moves effort to someone else.
Tiercel Labs helps engineering teams understand and improve what AI coding tools change: delivery speed, code quality, review effort, and cost. Raffay Sajjad leads the assessment and the implementation.
Generating code is one part of delivering software. Someone still has to understand the change, review it, test it, and maintain the system it joins. That is where we focus.
A faster first draft can coexist with larger PRs, more rework, or higher tool spend. Whether that tradeoff is worthwhile depends on the team, the task, and the evidence. We help engineering leaders examine those tradeoffs in their own workflow.
The starting point is a small, fixed-scope assessment. We establish a baseline, identify the friction, and implement one agreed improvement. Further work follows from the findings.
Optimizing one number can hide a problem elsewhere. We examine the complete path from a task to accepted, maintainable code.
Task-to-merge time, reviewer effort, retries, and handoffs. We look for where AI-assisted work saves time and where it moves effort to someone else.
Duplication, abstraction reuse, architecture drift, code churn, and CI failures. Findings come from reviewing changes in the context of the repository.
Tool spend, model choice, context overhead, and human review. We weigh the cost of a usable result against quality and operating constraints.
A founder-led practice with a bounded first engagement, direct communication, and findings your team can inspect.
Raffay runs the assessment, reviews the code and workflow, and implements the agreed change. Technical questions stay with the person doing the work.
We use available usage data, representative changes, and developer interviews. Every finding distinguishes observations, estimates, and unanswered questions.
Begin with one team and one repository. Agree the evaluation questions, access, deliverables, and fixed fee up front. Broader implementation is a separate decision.
You receive the baseline, prioritized findings, agreed configuration or code changes, and a measurement runbook. Your team can repeat the checks and decide what to do next.
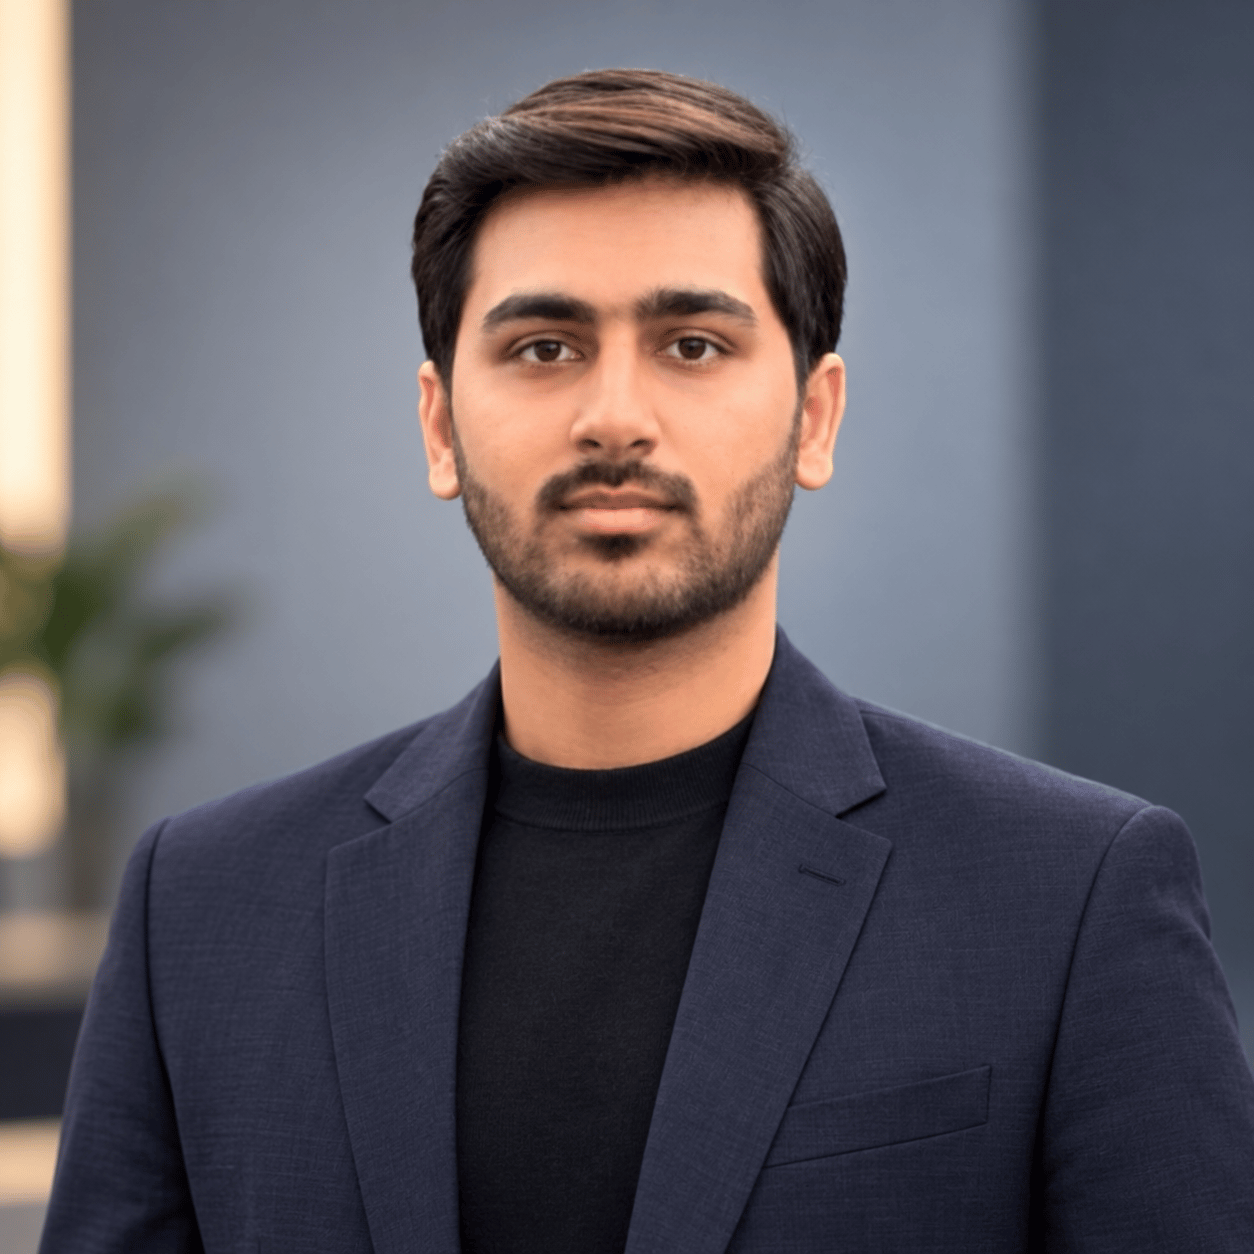
Founder · Technical lead · Hands-on engineer
Raffay brings technical leadership at Trafilea across architecture, delivery, experiments, and production systems. That background informs how he examines changes across a team and a codebase.
He built Finly AI end to end, spanning mobile applications, backend services, infrastructure, and analytics. Building and operating a product gives the assessment a practical grounding in the consequences of engineering decisions.
His current focus is agentic development: context and repository instructions, generated-code quality, model selection, local models, and the economics of retries and review. Tiercel brings that work into a focused assessment for engineering teams.
These are founder credentials and areas of practice. They are not claims of client audit outcomes or guaranteed savings.
Generated lines and accepted suggestions are activity signals. Review, rework, and maintainability belong in the assessment of delivery.
A cheaper model is only useful if it meets the task's requirements. We include retries, review effort, and local infrastructure where relevant.
PR history alone cannot reliably identify AI-written code or show that AI caused a performance change. We document those limits and avoid false precision.
We agree what evidence is needed before requesting access. Redacted exports and guided walkthroughs are alternatives when direct repository access is unsuitable.
An instruction update or model switch should be checked on representative tasks. The handover includes a plan to evaluate its effect after the assessment.
Findings, agreed code or configuration, and runbooks stay with you. Continuing with Tiercel is an option, not a dependency built into the delivery.
The best fit is an established software team using coding assistants or agents, with a concrete question about delivery, code quality, or spend and an internal owner for the work.
You need an evidence-based view of AI tooling investment, its tradeoffs, and where the next improvement is worth making.
You see larger changes, review bottlenecks, or inconsistent agent output and want to understand what is happening in the team's day-to-day work.
You own shared tooling, repository instructions, model access, or CI checks and need a focused assessment of how those pieces work together.
Team size is less important than a real workflow, usable evidence, and someone who can act on the findings. This offer is focused on engineering teams already using AI coding tools.
Choose one team, one repository, and the decisions the assessment should inform. Confirm available data, minimum access, the fixed fee, and the timeline.
Review representative PRs, tool or usage exports, CI history, agent configuration, and team interviews. Record evidence gaps alongside the measurements.
Prioritize findings by likely impact, effort, and confidence. Implement one bounded workflow or configuration change agreed in the scope.
Walk through the findings, hand over the changes and runbook, and define how to evaluate the result. Scope any larger implementation separately.
Fixed-scope assessment, typically one to two weeks after access is ready
Raffay owns the assessment, agreed implementation, and handover
AI-assisted delivery, code quality, agent configuration, and workflow economics
A baseline, prioritized findings, one bounded improvement, and a repeatable evaluation
Tiercel Labs is operated by RAFFAY LLC. Engagements are delivered remotely.
Tell us which coding tools your team uses and what you need to understand about cost, review, or delivery. We will help scope a useful first assessment.